2.9 Quantexa Upgrade Guide
Table of Contents Quick Upgrade Overview Community Upgrade Guidance Dependencies and Platform Modernisation User Interface Changes Pre-built Images and Pre-packaged Artifacts Backend and Data Pipeline Changes Data Packs Migration Recent Deprecations Software Compatibility Additional Information Quick Upgrade Overview The 2.9 Quantexa Upgrade consists of five main parts: Dependencies and Platform Modernisation User Interface (UI) Changes Pre-built Images and Pre-packaged Artifacts Backend and Data Pipeline Changes Data Packs Migration The 2.9 release is one of the most structurally significant Quantexa upgrades to date. The headline change is the move to pre-built Docker images for App Tier applications. Rather than compiling application modules project-side, projects now use the Image builder plugin to layer project-specific extensions onto Quantexa-provided base images. This fundamentally changes the build and deployment model and drives many of the API refactoring changes across the platform. On the dependencies side, this release involves major framework upgrades: Gradle 9, Spring Boot 4, Node.js 24, and Angular 21. Elasticsearch 7 and OpenSearch 1, deprecated in 2.8, have been fully removed - projects must be on Elasticsearch 8/9 or OpenSearch 2. Elasticsearch 9 is newly supported. While the Repository Tool handles most of the automated migration, projects with custom Gradle build code, custom Spring configuration, or custom UI code should budget additional manual effort. The User Interface tier includes many configuration restructuring changes. Global UI configuration, Explorer dynamic configuration, and Search 2 configuration all move to versioned directory-based formats. The Home Page reaches General Availability (GA), several Investigation modules are removed, and PrimeNG is replaced with a Quantexa-maintained fork. Data Packs 2.3.x remain compatible with Quantexa 2.9 and require Parsers 4.2.3 or later. This page provides additional guidance for the 2.9 Quantexa Upgrade. For the full list of required migration steps, please refer to the Documentation site migration guide: 2.8 → 2.9 Upgrade Migration Guide. Release Notes: Community Release Announcement 2.9 Release Notes Community Upgrade Guidance Dependencies and Platform Modernisation Gradle 9 Upgrade This is one of the most impactful changes in the 2.9 upgrade. Gradle 9 removes several build script APIs and tightens behavioural rules that previously generated only deprecation warnings. The Repository Tool automates the migration for patterns used in Quantexa-generated build files, covering changes such as replacing configurations.all with configurations.configureEach, updating archivesBaseName to archiveBaseName.set(), and reordering sourceSets blocks. However, deployments with custom Gradle build code will almost certainly require additional manual changes. After the automated migration, run ./gradlew build and resolve any remaining failures. Common follow-up tasks include replacing usage of removed org.gradle.util.CollectionUtils methods and reviewing any include directives that the migration commented out in settings.gradle. Spring Boot 4 Upgrade The mid-tier has been upgraded from Spring Boot 3.x to Spring Boot 4.0, introducing breaking changes for all deployments. A Scalafix rule handles Scala source file migrations, and a Plop migration covers common changes such as relocating configuration keys (server.error → spring.web.error) and updating Spring Boot imports. However, the Plop migration cannot cover every Spring Boot 4 scenarios, especially for custom code. After running the automated migrations, manually review the official Spring Boot 4.0 Migration Guide for any additional changes your deployment requires. Note that moving to pre-built images also eliminates many Spring bean extension points, replacing them with Scala singleton objects (see Pre-built Images section below). Elasticsearch 7 and OpenSearch 1 Removed Following their deprecation in 2.8, Elasticsearch 7 and OpenSearch 1 have been fully removed. Deployments still on ES7 must upgrade to Elasticsearch 8 or 9 before upgrading to 2.9. Deployments on OpenSearch 1 must upgrade to OpenSearch 2. Elasticsearch 9 is now supported alongside Elasticsearch 8. Quantexa recommends upgrading to ES9 for the latest performance and security improvements. However, note the following limitations in 2.9.0: EmbeddedElasticServer is not supported for ES9 - deployments using it for local testing must migrate to Docker-based Elasticsearch Offline Indexing is currently not supported with ES9 OpenSearch 3 is not supported in this release The elastic*-builder NPM packages used by the UI for ES7 query building have also been removed. Node.js 24 and Angular 21 Node.js has been updated from version 22 to 24 (required by Angular 21). Angular has been updated to version 21. Plop automatically handles the UI code migration. As with the 2.8 Angular upgrade, Plop may fail to migrate package-lock.json to a consistent state - if you encounter UI build errors, delete node_modules and package-lock.json from the web-app folder and run npm install to regenerate them. Ensure all CI/CD pipelines, development environments, and Docker build stages reference the new Node.js version. User Interface Changes Home Page (General Availability) The Home Page reaches General Availability in 2.9, providing a configurable landing page with widgets for quick access to recent activity, tasks, and investigations. A Plop migration is available for initial setup. Projects should review their Home Page configuration and test the landing experience post-migration. Investigation Modules Removed The Investigation modules deprecated in 2.8 (replaced by Resource Viewer) have been fully removed. The affected modules include CompoundGraphViewModule, SourceViewerPluginModule, RecordViewerPluginModule, and others. A Plop migration handles the removal. Projects should have already migrated to Resource Viewer during the 2.8 upgrade. Additionally, the Custom Bulk Search component has been removed - Bulk Search configuration is now fully managed through the standard configuration approach. Global UI Configuration Migrated to Versioned HOCON The Global UI configuration has been restructured from a monolithic JSON file to a versioned directory containing HOCON configuration and a version.conf file declaring the schema version. This enables automatic schema migration during platform upgrades. Plop creates a config/global-ui/ directory structure and updates application.yml paths. Several previously unused fields (validFrom, validTo) have also been removed. Projects must verify that deployment manifests (Helm Chart or QAT) are updated to mount the new directory as a ConfigMap volume. Explorer and Search 2 Configuration Split Explorer dynamic configuration has been split from a single monolithic file into per-schema .conf files within an explorer-dynamic-configuration/ directory, with an index.conf file. Search 2 configuration follows the same versioned directory pattern, migrating from a single JSON file to config/search2/ containing search2-dynamic-config.conf and version.conf. Both Plop migrations handle the conversion, update application.yml paths, and add ConfigMap entries to deployment scripts. Projects must verify that the updated volume mounts are present in their deployment manifests. PrimeNG Fork and Dependency Cleanup PrimeNG has been replaced with @quantexa/primeng-fork, a Quantexa-maintained fork. All primeng/* imports in TypeScript, CSS, and SCSS files must be updated - a Plop migration handles this automatically. Additionally, Web Core peer dependencies have been removed from project-level package.json and are now managed by the @quantexa/web-core package. After migration, regenerate package-lock.json by deleting node_modules and the lock file, then running npm install. To keep dependency overrides up to date between major releases, use the src:cve-update script. The project-level ESLint configuration and its dependencies have also been removed. Projects that require ESLint must configure it independently. UI script and import paths have been updated: the lint, src:migrate-scss, and eslint-config:link scripts are removed, and @quantexa/script-lib imports must be updated to @quantexa/utils and @quantexa/build-tools. Alternative Network Layouts (General Availability) Alternative Network Layouts, which provide different ways to visualise entity networks, reach General Availability in 2.9. A Plop migration renames edge configuration properties. Projects using custom network layout configuration should review the updated property names. Localisation Configuration Restructured The localisation configuration has been restructured for multi-language support. This is a breaking change with Plop migration support. Projects should verify their localisation setup post-migration. Low-Code Configuration (LCC) Validation Tests LCC validation tests have been migrated to a new location. A Plop migration updates test locations and imports. Continue to run configuration validation tests early in the upgrade process to catch configuration errors before deployment. Pre-built Images and Pre-packaged Artifacts Application Pre-built Docker Images This is the most architecturally significant change in 2.9. Applications are no longer compiled project-side. Instead, Quantexa provides pre-built Docker images for App Tier services (all applications except the UI and app-fusion). Projects use the Image builder plugin to layer project-specific extensions onto these base images. The migration involves seven steps, which must be completed in order: Migrate application extensions to dedicated modules (Manual) - custom code in application modules (e.g. app-security/src/main/, app-investigate/src/main/) must be moved to dedicated extension modules with recognized naming conventions that the Image builder plugin auto-discovers. Register Foreign Documents for Fusion data configuration (Manual) - applications now read data configuration from fusion-data-config.json rather than compiled Scala models. Foreign Documents not automatically included must be registered via .qdocuments and .qmodel files. Migrate SAML metadata files (Plop) - the classpath: protocol for SAML metadata is no longer supported; XML files must be moved from app-security/src/main/resources/ to a mounted config/saml/ directory. Migrate optional modules to feature flags (Plop) - optional service dependencies in build files are replaced with feature flags in deployment configuration. Add Image builder plugin configuration (Plop) - adds the plugin to the root build and creates the applications.gradle file. Migrate each application to pre-built images (Plop) - replaces each application module with a .gitkeep, updates settings/libraries/applications Gradle files. Update deployment configuration (Manual) - applications with project-specific extensions are renamed with a -project suffix (e.g. app-resolve becomes app-resolve-project). Deployment configuration must reference the new names. This migration has a cascading impact across the platform. Many of the API changes in Visualization and Exploration (see below) are directly driven by this change - extension points that previously relied on Spring bean registration in compiled application modules must now use Scala singleton objects in dedicated extension modules. Projects should follow the Application Pre-built Image Migration Guide carefully. For projects that need help adopting container-based deployment, speak to your Quantexa Architect. They can help assess your current deployment model and plan the transition to pre-built images. Impact on Local Development The move to pre-built Docker images changes the local development workflow. Previously, developers could run mid-tier applications locally using bootRun or java -jar commands. With pre-built images, these applications are no longer compiled project-side, so the traditional local run scripts no longer apply for most App Tier services (the UI and app-fusion are still built project-side). There are three options for development workflows going forward: Cloud-based or development environment development (recommended) - develop against a shared or personal Kubernetes development namespace with CI/CD pipelines configured for rapid iteration. This is the approach Quantexa uses internally and is the recommended path. Projects should work with their Quantexa Architect to set up development namespaces that support concurrent developer activity, including sizing the environment to handle multiple developers working in parallel. Local container-based development - use Minikube, Docker Desktop, or an equivalent local Kubernetes environment to run pre-built images on a developer laptop. This preserves the ability to work locally but requires container tooling to be available on the development machine. The overhead of Docker itself is relatively low, but the growing footprint of the full application stack may be challenging on lower-specification machines. Projects should verify that laptop or VDI specifications are sufficient for this approach. Pre-built boot JARs (fallback) - pre-built Spring Boot JARs are available for projects that cannot adopt container-based development locally. However, this means local development uses a different deployment pattern to higher environments, requiring the project to maintain two deployment approaches and accept the risk of environment divergence. The same structural migration steps (dedicated extension modules, Image builder plugin configuration) still apply to ensure compatibility with repository migrations in later Quantexa versions. Projects upgrading to 2.9 should factor the development workflow transition into their migration effort estimates. For environments with strict change management requirements where cloud-based development namespaces are not readily available, discuss options with your Quantexa Architect early in the upgrade planning process. Pre-packaged Batch Shadow JARs Quantexa now provides pre-packaged shadow JARs for Batch tier tasks, eliminating the need to compile batch platform code from source. A Plop migration updates project structure and build configuration. Projects with custom batch tasks should review the migration to ensure their custom tasks integrate correctly. Backend and Data Pipeline Changes Data Fusion and ETL Several changes affect the Data Fusion and ETL pipeline: ENGFull renamed to BatchFull (Plop) - generated ETL script classes have been renamed from ENGFull{Model}ETLScript to BatchFull{Model}ETLScript. Template files have similarly changed from runAllENG.sh to runAllBatch.sh. Metadata excluded from hash ID calculation (Plop) - the metaData field is now excluded from hash ID computation by default when using hashIdField configuration. This improves Entity Resolution (ER) stability during incremental ETL runs. To preserve the previous behaviour, add metaData to the including list in your hash ID configuration. fusion-spark-utils removed - projects using this library must migrate to the replacement APIs. Document type validation against Fusion config (Manual) - document type definitions in Resolver configuration are now validated against Fusion configuration at startup. If a Document type is defined in Resolver but missing from the corresponding .qdocuments file, the application will fail to start with an IllegalStateException. Resolver and Batch Resolver Several Resolver APIs have been cleaned up: liftAttributes removed (Manual) - the liftAttributes configuration option has been removed without replacement. This changes how Record Attributes with mixed types are handled across Document types. Projects should check Batch Resolver logs for Record attributes to lift: entries to identify impact. Path methods removed (Manual) - several Path convenience methods have been removed from the Batch Resolver API. Resolver configuration cleanup (Plop) - several deprecated fields have been removed: dataModelRootClass, dataModelRecordExtractor, intelligenceModelClass, intelligenceModelExtractor from document/intelligence definitions; icon from entity definitions; availableIcons from UDI document definitions. Entity Store Key changes to the Entity Store: Custom External Attributes (Manual) - must now be defined in a dedicated custom-external-attributes module and configured via the external-attributes.calculations-object property. Previously, these could be defined in any module and injected as a Spring Bean. Custom Attribute Functions: ValidatedNel → Either (Manual) - the return type has changed from ValidatedNel to Either[List[String], T], and the expectedFields and name variables have been removed from the relevant traits. Custom Data Quality Functions (Manual) - the EntityQualityCheckAggregation interface now requires usedEntityAttributes and usedRecordAttributes properties. Error handling changes (Manual) - the Entity Store REST API now returns clearer error responses (validation errors return 400, timeouts return 503). Deployments with custom error handling logic must update their implementation. Change Log metadataPath (Plop) - Entity Store Change Log, CRUD Log, Document Log, and Batch ETL to Stream scripts now require a metadataPath configuration property. Scoring The elastic*-builder Gradle dependency has been removed. The Scoring Dynamic subproject requires migration to a new structure; follow the Scoring Dynamic Subproject Migration Guide. Both have Plop support, but deployments with custom Scoring configuration should review changes carefully. Data Integration Several Data Integration changes: Kafka Ingest error handling configuration (Manual) - error handling configuration has been refactored as part of the pre-built image migration, moving to a dedicated extension module. RecordExtractionModelConfig refactored (Manual)-RecordExtractionModelConfig has been replaced by RecordExtractionModelConfigBuilder. Search Related Entities configuration (Manual) - configuration has been updated as part of the pre-built image migration. Combined Ingest service removed - the combined ingest service has been fully removed. DatasourceTestSpec deprecated - DatasourceTestSpec is deprecated in favour of ETLTestSpec. Additionally, Elasticsearch-backed data source integration tests (GenericFullEtlRun ES variants) have been removed. Q AI - Q Assist Q Assist Workspace Agents reach Public Preview in 2.9. LLM configuration for Q Assist has been updated - projects using Q Assist must review and update their LLM provider configuration. This is a manual change. Decision Systems Decision Systems 2.9.0 includes breaking changes. Key changes include: initialTaskGraph is now required, Hub and Spoke Scores have been removed, and Contextual Data Mapping has been converted to Monitored Data. See the 2.8 → 2.9 Decision Systems Migration Guide for step-by-step guidance. Data Packs Migration Data Packs 2.3.x are compatible with Quantexa 2.9.x and require Parsers 4.2.3+, 4.3.x, or 4.4.x. Parsers 3 has not been supported since Quantexa 2.8. If your project has not yet completed the Parsers 4 migration, complete it before upgrading. For planning and step-by-step guidance, see: Why & How to Plan a Parsers 4 Migration Step-by-step Guide to Migrate to Parsers 4.3 There are no Data Packs-specific breaking changes in the 2.9 upgrade beyond what is covered by the platform migration. Projects already on Data Packs 2.3.x with Parsers 4 can continue using the same version. For the full Data Packs compatibility matrix, see Data Packs Compatibility Matrix. Recent Deprecations PyQSS Import Path The PyQSS import path has been deprecated. Projects using PyQSS should update their imports to the new path. I/O Handler Environment Variables I/O handler environment variables have been deprecated in favour of updated configuration. smart_open Library The smart_open library has been deprecated. icon Property in Resolver and Fusion Document Definitions The icon property in Resolver and Fusion Document definitions is deprecated. While the property still functions, it will be removed in a future release. DistinctValue for List Type Fields Using DistinctValue for List type fields is deprecated. DatasourceTestSpec The DatasourceTestSpec class is deprecated in favour of ETLTestSpec. Bundled libpostal Bundled libpostal in app-kafka-record-extraction and app-search-related-entities images is deprecated. Projects relying on the bundled version should plan to provide their own libpostal installation. transliterateElements The transliterateElements configuration has been deprecated. Software Compatibility Check software compatibility. Key changes for 2.9: Apache Spark: 3.5.x Java JDK (Application Tier): 17 Node.js: 24.15.0 (upgraded from 22) npm: 11.12.1 (upgraded from 10.9.0) Gradle: 9.3.1+ (upgraded from 8.4+) Elasticsearch: 8 and 9 (ES7 removed); OpenSearch 2 (OS1 removed) Redis / Valkey: Redis 6.x, 7.x, 8.x and Valkey 7.x, 8.x, 9.x (now mandatory) Kafka: 3.x, 4.x CPython: 3.11.x, 3.12.x (3.10.x removed) Scala: 2.12 MySQL: 8.x, 9.x PostgreSQL: 13.x to 18.x Additional Information Useful resources: Upgrade Best Practice for instructions before commencing an upgrade. Ongoing development during upgrades for best practice guidance on continuing with meaningful development during an upgrade. Quantexa Upgrade Knowledge Hub for comprehensive guidance on planning and executing upgrades. Application Pre-built Image Migration Guide for the step-by-step guide to migrating to pre-built Docker images. Scoring Dynamic Subproject Migration Guide Angular 21 Migration Guide Upgrading from Elasticsearch 8 to Elasticsearch 9 2.8 → 2.9 Decision Systems Migration Guide 2.9 Release Note Walkthrough video walkthrough of the 2.9 release. Parsers 4 Migration Guidance for planning and executing the Parsers 4 migration. Data Packs Compatibility Matrix Follow the Release Announcements Topic to receive notifications of releases. Quantexa Release Notes for changes and information specific to different versions of Quantexa.231Views0likes0Comments🚀 Launching Soon: Data Scientist Community User Group 🚀
We're excited to be launching a new space for data scientists to connect, share knowledge, and learn from each other. Whether you're looking to exchange ideas, discuss challenges, discover best practices, or build new connections, this community is for you. Visit here to request to join. By signing up now, you'll become one of our first members when the group goes live. See you in the group! P.S. Interested in Data Science? Don't miss our upcoming event: Data Science & Real-World Context in the Age of AI128Views0likes0Comments
Achieve a True 360° View with Quantexa Unify for Microsoft Fabric, now GA
Today, we announced the General Availability (GA) of Quantexa Unify, an AI-powered integration within the Microsoft Fabric platform that connects fragmented data at scale with speed and precision. Read our step-by-step guide on how we’re helping users create AI-ready, entity-resolved data in minutes that can deliver true 360 degree views directly into end-user applications for smarter decision-making. An enterprise 360-degree view gives organizations comprehensive visibility of their operations. It involves creating unified views of an organization's data across all departments, systems, and processes, helping integrate, analyze, and act on data holistically for better decision-making, risk management, and customer insights. It underpins industry use cases such as Customer 360 in marketing intelligence, Citizen 360 in government or Patient 360 in healthcare. With OneLake in Microsoft Fabric, organizations have a strong foundation for unifying and delivering data. OneLake collates data across silos and delivers it with ease directly into your data pipelines and business operations, overcoming challenges organizations have faced with traditional Master Data Management approaches. This includes issues like servicing distinct business needs and data acquisition strategies with disparate systems, while maintaining data consistency. However, more data can mean more duplicates, incompletions and inconsistencies which can disrupt pipelines, and prevent accurate data reaching your business when you need it. For this, Quantexa Unify, a native Microsoft Fabric Workload, now GA, adds a simple-to-use entity resolution capability. It is grounded on proven experience in the world’s largest and most demanding organizations as part of the Quantexa Decision Intelligence Platform, fundamental to applications like customer intelligence, risk identification, and event monitoring where accuracy and context matters. Let’s explore how Quantexa Unify for Microsoft Fabric can deliver de-duplicated data, through dashboards, notebooks and data pipelines and platforms, drawn from across your Fabric data estate. Providing accurate, contextual enterprise 360-degree views of individuals, organizations, locations, and other real-world entities in your Fabric tenant, ensuring PII and your data privacy compliance. Run the native workload Add the Unify workload to your Fabric tenant. From the Microsoft Fabric home page, click the Workloads button in the left navigation page. From the Add more Workloads section, click the Quantexa Unify workload to add it to your tenant. Once added, the workload appears on the My Workloads section on the same page. You are good to go! Before you create your project, ensure the Data Sources you want to use with the workload are in a suitable format to upload as lakehouse objects to Fabric. Now select the data sources. Unify will analyze the metadata, and identify the content of the data fields, then automatically map those fields to pre-defined entity resolution models. Now in a few clicks we can organize our Enterprise 360 view through optimizing data mapping and selecting our entity resolution preferences for matching that meets your needs and schemas. We’ll start by mapping data across the data sources in OneLake. Once your Data Sources are mapped, you can now resolve and create matched Entities by running an Iteration where the power of entity resolution is highlighted. In the video, we selected the default option. A sales team or an investigation team may prefer more open-ended “fuzzy” record matching view while a finance team or a marketing team adhering to GDPR may take a “strict” view. The process takes only a few minutes, with most time spent on the computational overheads of setting up the jobs. Whether handling 1 row, a thousand rows or 100 million, execution time grows only marginally, delivering near-constant performance at scale. The Quantexa Platform has been proven at 60 billion+ record volumes. It scales to the size of your OneLake data estate. You - the user - control the capacity (amount of compute), and hence you can control the performance. Power your Microsoft Fabric data pipeline Now take your accurate, deduplicated data into your end-user applications, for example: Power BI for dashboards and analysis Fabric Data Warehouse for data warehouse teams and administering data products Fabric Notebooks for data science and reporting, including Python and R Microsoft Copilot-enabled Fabric data workflows Without entity-resolved data, issues arising from unmatched, disconnected data could lead to: duplicated entries skewing statistics incorrect classifications and categorizations false positives arising from seemingly independent records that were not. Instead, when building your next data product, or using Microsoft’s predict function in a Fabric notebook, or populating your Power BI dashboard, ensure your data is AI-ready with entity resolution and Quantexa Unify. Get Started Today! Find the workload on Microsoft Fabric!218Views0likes0Comments
How Decision Systems 2.8.3 integrates with Data Viewer and Explorer
We’re excited to announce that Data Viewer and Explorer are now fully integrated into Decision Systems with version 2.8.3. Why This Matters Data Viewer helps investigators and analysts explore and filter data efficiently during investigations. Data Viewer uses the Explorer API to query data sources and present them in a structured, interactive format. This means: Investigators and analysts can automatically replicate score logic, saving time, minimizing errors, and delivering scale. Score logic is more easily represented, for intuitive filtering of relevant transactions. Complex scores are more easily investigated. How Data Viewer and Explorer work with Scores When an investigator selects a score, Data Viewer and Explorer can display all transactions that triggered that score. Transactions can be shown via queries or transaction IDs. Using queries allows investigators to see the queries in Explorer for deeper investigations beyond the original score. Benefits of integration with Decision Systems Faster implementation: Saves ~0.5 days per score—no longer need to set up Data Viewer and Explorer manually. Reduced maintenance: Queries are automatically sent to Data Viewer and Explorer—no need to manually replicate score logic or update UI queries after tuning. Accuracy and confidence: Automated integration ensures correct transactions are displayed to investigators in Data Viewer and Explorer. Improved user experience: Queries can be explored and amended in Explorer; Data Viewer now supports all scores. Explainer videos Watch these short videos to learn more: 01 Data Viewer and Explorer See how the integration appears in the UI and learn how to configure Data Viewer and Explorer. 02 Data View Integration Setup Understand the data ingestion requirements for using Data Viewer and Explorer effectively.209Views3likes0CommentsDefine Your Upgrade Approach
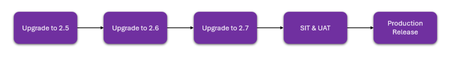
Having created your Upgrade Roadmap, the next critical decision is to define how you will execute the work. There are two fundamentally different strategies for upgrading your Quantexa platform: the Incremental Upgrade and the Reset Upgrade. This page will guide you in selecting the right approach for your specific context, considering factors like your roadmap's complexity, your solution's health, and your team's capacity. At a Glance: Comparing the Approaches Approach Key Characteristic Best For... Primary Benefit Key Consideration Incremental Upgrading through each major version sequentially ("hopping"). Solutions that are well-aligned with Quantexa best practices and are only a few versions behind. Efficiency. Maximises automation using the Repository Tool. The Repository Tool is less effective on solutions with high technical debt. Reset Creating a new, clean repository on the target version and migrating code selectively. Solutions that are many versions behind or contain significant technical debt. Clean Slate. An opportunity to remove technical debt and realign to best practices. Higher initial manual effort to set up and selectively migrate logic. In-Depth: The Incremental Upgrade This is the most common and efficient approach. It involves upgrading your existing repository through each major version between your current state and your target destination. For example, moving from v2.5 to v2.8 would involve separate, sequential upgrades to v2.6, v2.7, and finally v2.8. This approach makes maximum use of Quantexa's Repository Tool, which is designed to automate much of the migration effort between sequential versions. This is the default and recommended option if you are only upgrading a single major version (e.g., from 2.7 to 2.8). When performing an incremental upgrade across multiple versions, you have two release strategy options: Option 1: Single Go-Live Perform each version "hop" in quick succession within your development environment, but combine them into a single release package. This package goes through one cycle of SIT, UAT, and Production deployment. Benefits: Reduced Testing Overhead: One round of formal SIT/UAT saves significant time and effort. Faster Time-to-Target: Achieves the final goal of deploying the target version in the shortest overall project duration. Developer Efficiency: Developers build deep expertise by performing the "hops" back-to-back, increasing speed. Option 2: Staged Go-Live (Release per Hop) Treat each version "hop" as a mini-project. You develop, test (SIT/UAT), and release each incremental version to Production before starting the next hop. Benefits: Lower Risk per Release: Each deployment is smaller and more contained, simplifying testing and root cause analysis if issues arise. Incremental Value: End-users can benefit from new features and improvements more regularly. Increased Flexibility: Allows your team to address other business priorities between upgrade stages. In-Depth: The Reset Upgrade This approach involves creating a brand-new, empty repository on the target platform version. Your team then selectively migrates or completely rebuilds the required logic (data interfaces, Entity Resolution, Scoring, etc.) from the old repository into the new one. This is a strategic choice to "pay down" technical debt. Benefits: Your implementation is multiple major versions behind the latest Quantexa Platform release. The current solution contains a high degree of technical debt, making an incremental upgrade complex and risky. You need to make significant architectural changes or re-align to modern Quantexa best practices. While this approach requires more upfront manual effort, it ensures that your repository is clean, modern, and optimized for future scalability and smoother upgrades. How to Choose Your Approach Your choice will depend on the specifics of your Quantexa deployment and the goals of your upgrade. If your solution is well-aligned with best practices and your Upgrade Roadmap involves only one or two hops, the Incremental approach is almost always the best choice. If your solution suffers from significant technical debt or your Upgrade Roadmap spans many major versions, the Reset Upgrade approach offers a powerful opportunity to reset for the future, even if the initial effort is higher. Quantexa's Divergence Tool can help provide insights into how far away from best practice the deployment is in certain areas The output of this step is a clear, documented decision on the approach you will take. Action: State your chosen upgrade approach. Example: We will follow an Incremental Upgrade approach with a Single Go-Live release strategy.248Views0likes0Comments